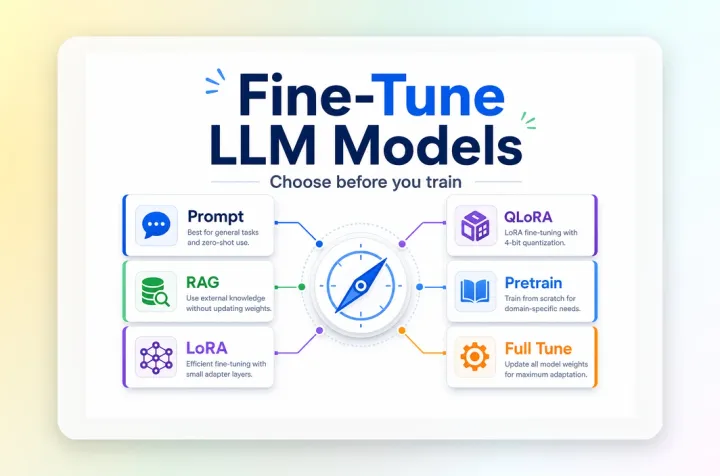
05 Aug 2026 How to Fine-Tune LLM Models: Choose the Right Method Before You Train Learn how do you fine tune lllm models by choosing between RAG, LoRA, continued pretraining, and full fine-tuning before training.
05 Aug 2026 Cloud GPU Performance LLM Training Hardware for 100B+ Parameters: Cluster Sizing, Buy-vs-Rent Decisions, and When to Stop at Experimentation Plan llm training hardware 100b+ parameters with cluster tiers, buy-vs-rent checkpoints, and GPU infrastructure guidance.
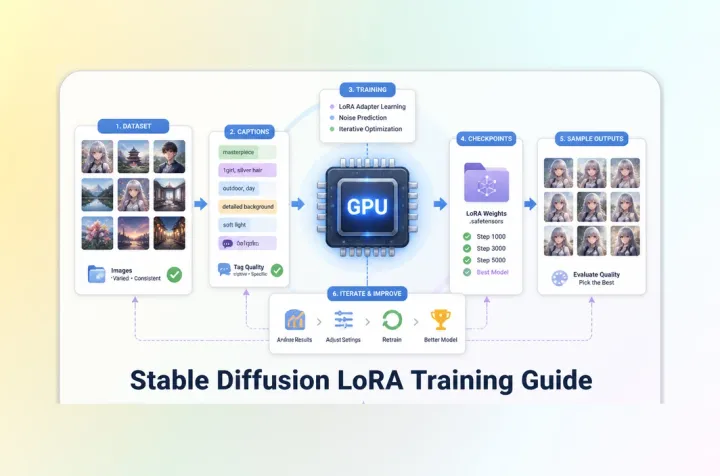
05 Aug 2026 Stable Diffusion LoRA Training Guide: Dataset, GPU Workflow, Parameters, and Troubleshooting Use this lora training guide stable diffusion workflow to plan assets, GPU setup, parameters, sample review, and reruns before deployment.
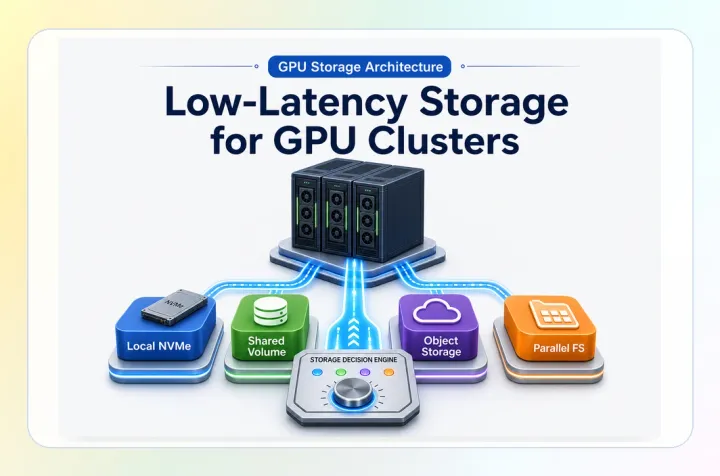
05 Aug 2026 Low-Latency Storage for GPU Cluster Deployments Choose low-latency storage for gpu cluster deployments by workload scale, artifact reuse, checkpoint needs, and RunC shared-volume fit.
05 Aug 2026 Share Cloud GPU Ollama Distributed Inference: What Is Possible, What Is Not, and When to Move Beyond Local Serving Learn where ollama distributed inference works, where it fails, and when to move from local Ollama to managed GPU deployment.